02 November 2026 · 8 min
AI training and robots.txt: prepare the shared signal properly
Google and OpenAI plan to support one shared robots.txt signal for AI training. It is not a finished standard and not universally live yet, but now is the right time to organize content classes, exceptions, and existing bot rules.
One signal for many providers — but not a switch for today
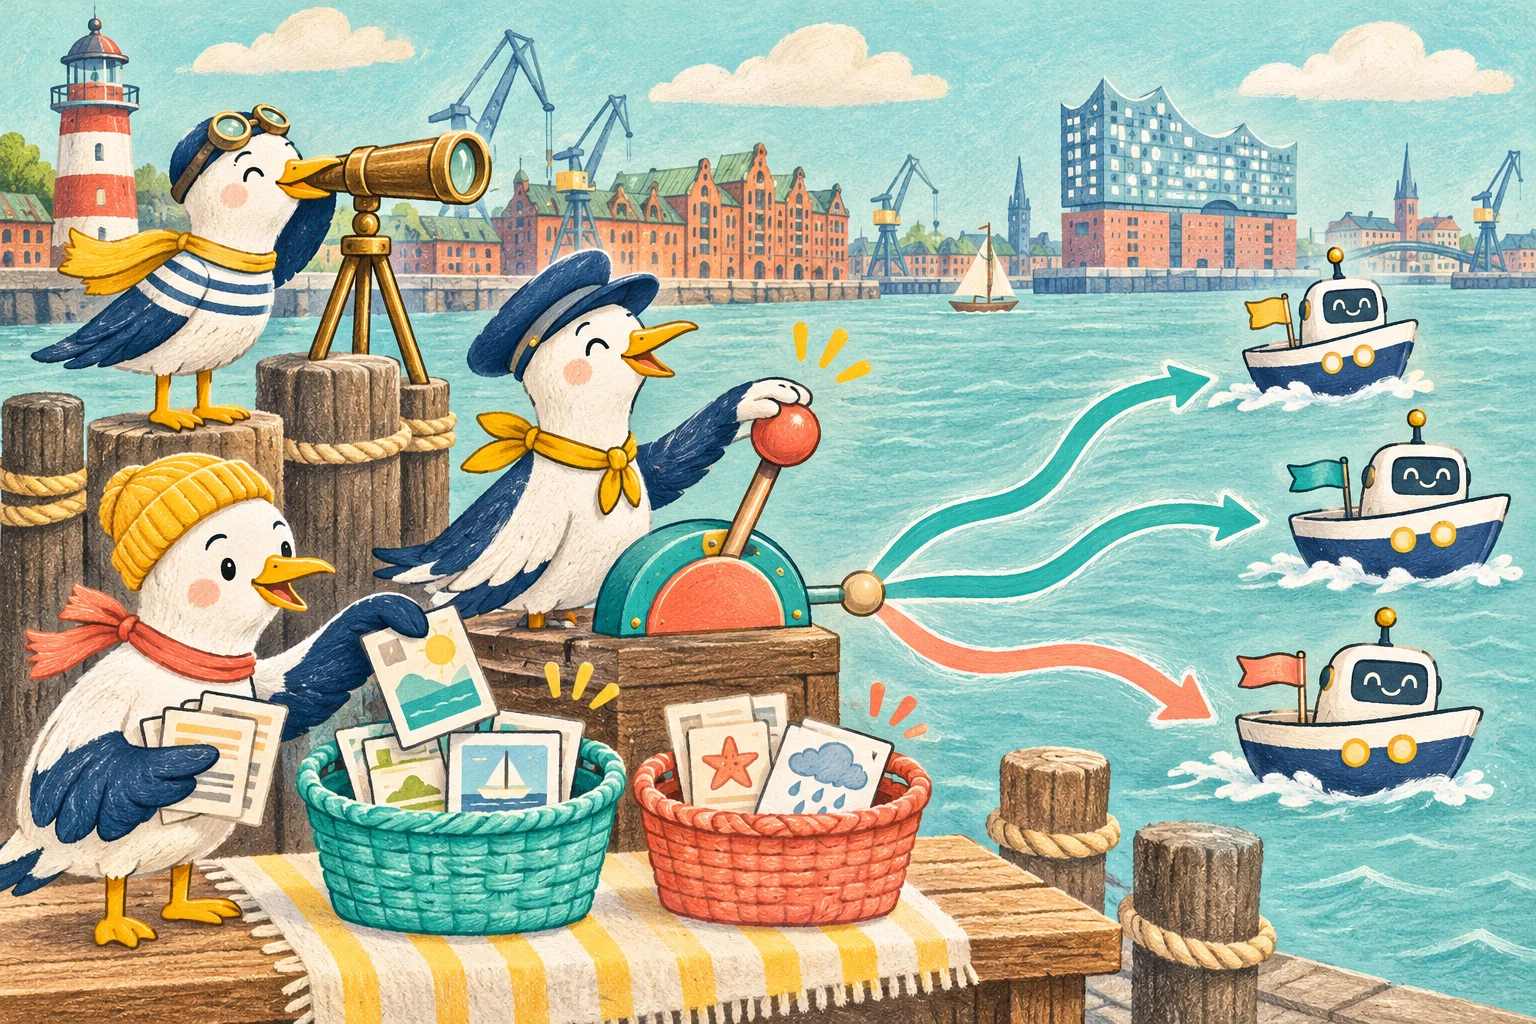
On October 30, 2026, Google and OpenAI announced plans to support a shared robots.txt signal for the use of web content in training generative AI models. The technical foundation is a new Internet-Draft from the IETF AI Preferences Working Group.
The idea is useful: instead of maintaining a separate rule for every provider, a website can express its preference through the shared policy token __usage_ai-training. Nobody should delete existing rules yet, however. The draft is work in progress, Google targets early 2027, and OpenAI says implementation should arrive in the coming months.
For website teams, this is not a copy-and-paste ticket. It is a good moment to settle three questions:
- Which content may be used to train generative AI?
- Which content should remain discoverable in search and AI grounding?
- Who decides, documents, and reviews these rules?
What the IETF draft actually defines
The draft does not introduce new robots.txt grammar. It uses ordinary user-agent groups, Allow and Disallow rules, and familiar longest-match behavior. The new element is a purpose-bound policy token:
User-Agent: __usage_ai-training
Disallow: /
Allow: /press-kit/
This example expresses a preference against AI training for the whole site while allowing it for content under /press-kit/. The draft defines AI training as using an asset to modify the learned parameters of a generative model. Pure classification, ranking, or scoring does not automatically fall under that definition.
One caveat matters: this is an individual Internet-Draft. The IETF explicitly says it has no formal standing in the standards process and may change or be replaced.
Usage preference is not crawl control
The most common misunderstanding will be: Disallow means the bot cannot fetch the URL. That is not automatically true for this policy token.
The draft separates two layers:
- crawler rules control whether a named crawler may retrieve a path;
- the policy token describes whether retrieved content should be used for a purpose.
Teams that need to limit crawling still need rules for the actual crawler tokens. The shared signal is a voluntarily interpreted usage preference. It is not access control or DRM, and it does not prevent unknown or non-participating crawlers from fetching public content.
Sensitive content belongs behind authentication, not behind robots.txt.
Separate Google Search, Google-Extended, and the new signal
Google documents Google-Extended as a standalone product token. It controls whether content already crawled by Google may be used for future Gemini models and for grounding in Gemini Apps and Vertex AI. Google-Extended has no separate HTTP user agent; it acts as control information in robots.txt.
Google explicitly says:
- Google-Extended does not affect inclusion or ranking in Google Search.
- When a site eventually opts out through the shared signal and does not explicitly specify Google-Extended, Google plans to treat it like a Google-Extended disallow.
- Specific Google-Extended rules will continue to work alongside the shared signal.
So search, training, and grounding are separate product decisions. One line should not decide all three without a business review.
Keep provider-specific rules for now
OpenAI says the new signal will not replace its existing crawler controls. Google makes the same point about provider-specific controls. Until implementations are live and tested, current rules for GPTBot, Google-Extended, ClaudeBot, and other providers remain the dependable layer.
A controlled transition looks like this:
- Inventory current groups and document their purpose.
- Prepare the shared token as an addition, not a replacement.
- Track each provider's announced start date and exact semantics.
- Verify behavior after rollout using published tests or provider documentation.
- Remove old rules only when equivalent behavior is demonstrable.
Deleting every proprietary group now would exchange maintenance work for a control gap.
Write a content policy before robots.txt lines
The syntax is short. The real work is deciding what may happen to content. We divide sites into practical classes:
- Public knowledge: blog posts, documentation, and help pages.
- Sales content: landing pages, product copy, pricing, and services.
- Brand assets: press images, logos, and approved descriptions.
- Protected work: client projects, licensed media, and paid content.
- User-generated content: comments, profiles, and community posts.
An owner should mark each class as allowed, disallowed, or undecided for training. Copyright, client contracts, licenses, and distribution strategy belong in the same conversation.
A blanket choice is convenient. A documented choice by content class is usually better.
Use path exceptions deliberately
The policy token supports paths. A brand can reject training for editorial articles while allowing an approved press kit. An open-source project might allow documentation while excluding a directory that contains third-party material.
Path rules become fragile when URL structure does not mirror ownership. Before using them, check:
- Is content clearly separated by purpose and rights?
- Can CMS editors accidentally move material into the wrong path?
- Do language or country sections carry different licenses?
- Are copies exposed through parameters, print views, or legacy URLs?
- Is the same robots.txt delivered after every deployment?
A preference is only as reliable as the URL architecture behind it.
A wildcard is not a shortcut
The IETF draft explicitly says that **User-Agent: *** must not be interpreted as a match for the policy token. A general disallow rule alone therefore does not express an AI-training preference under this mechanism.
The shared token needs its own explicit group. That also reduces the chance of blocking search crawlers when the intention was only to state a usage preference.
Precedence matters too. Provider-specific policy tokens may override general rules when that provider documents such behavior. Record that order in technical documentation and tests.
Treat robots.txt like configuration
Many sites generate robots.txt as an incidental text file. Once it carries product and usage choices, it becomes published policy configuration and deserves the same care as redirects or security headers:
- version the file in the repository;
- require review for changes;
- test syntax and expected groups in CI;
- fetch production after deployment;
- record date, owner, and decision rationale;
- monitor unexpected rewrites by the CMS, CDN, or hosting layer.
Every relevant origin needs its own review. A correct robots.txt on www.example.com says nothing about docs.example.com or an asset host.
What teams should do now
A useful November plan is small and reversible:
- Capture the current robots.txt from every relevant host.
- Label current search, training, and grounding rules separately.
- Record content classes and rights owners in a short policy document.
- Prepare the desired __usage_ai-training configuration in staging.
- Do not treat the shared token as a replacement for working provider rules yet.
- Schedule a review and provider checks for early 2027.
This makes the team ready without promoting an unfinished specification to production truth too early.
Our conclusion
A shared AI-training signal can save website operators a great deal of duplicated maintenance. Its greatest value, though, is not a shorter robots.txt file. It forces teams to treat training, crawling, search visibility, and grounding as separate decisions.
Teams that organize content and ownership now will be able to activate the new token deliberately. Teams that copy one line may have published a preference, but they still do not have a durable content policy.
Primary sources