29 September 2026 · 10 min
Self-hosted runners: one pipeline, one fresh machine
GitHub started fully enforcing self-hosted runner versions on 25 September. The better fix is larger than an update: make CI machines short-lived, isolated and reproducible.
When a pipeline suddenly does nothing but wait
On 25 September 2026, GitHub began fully enforcing minimum versions for self-hosted Actions runners. An outdated runner may no longer register or receive jobs. Every runner release — major, minor or patch — starts a 30-day window. A critical security update can stop job assignment sooner.
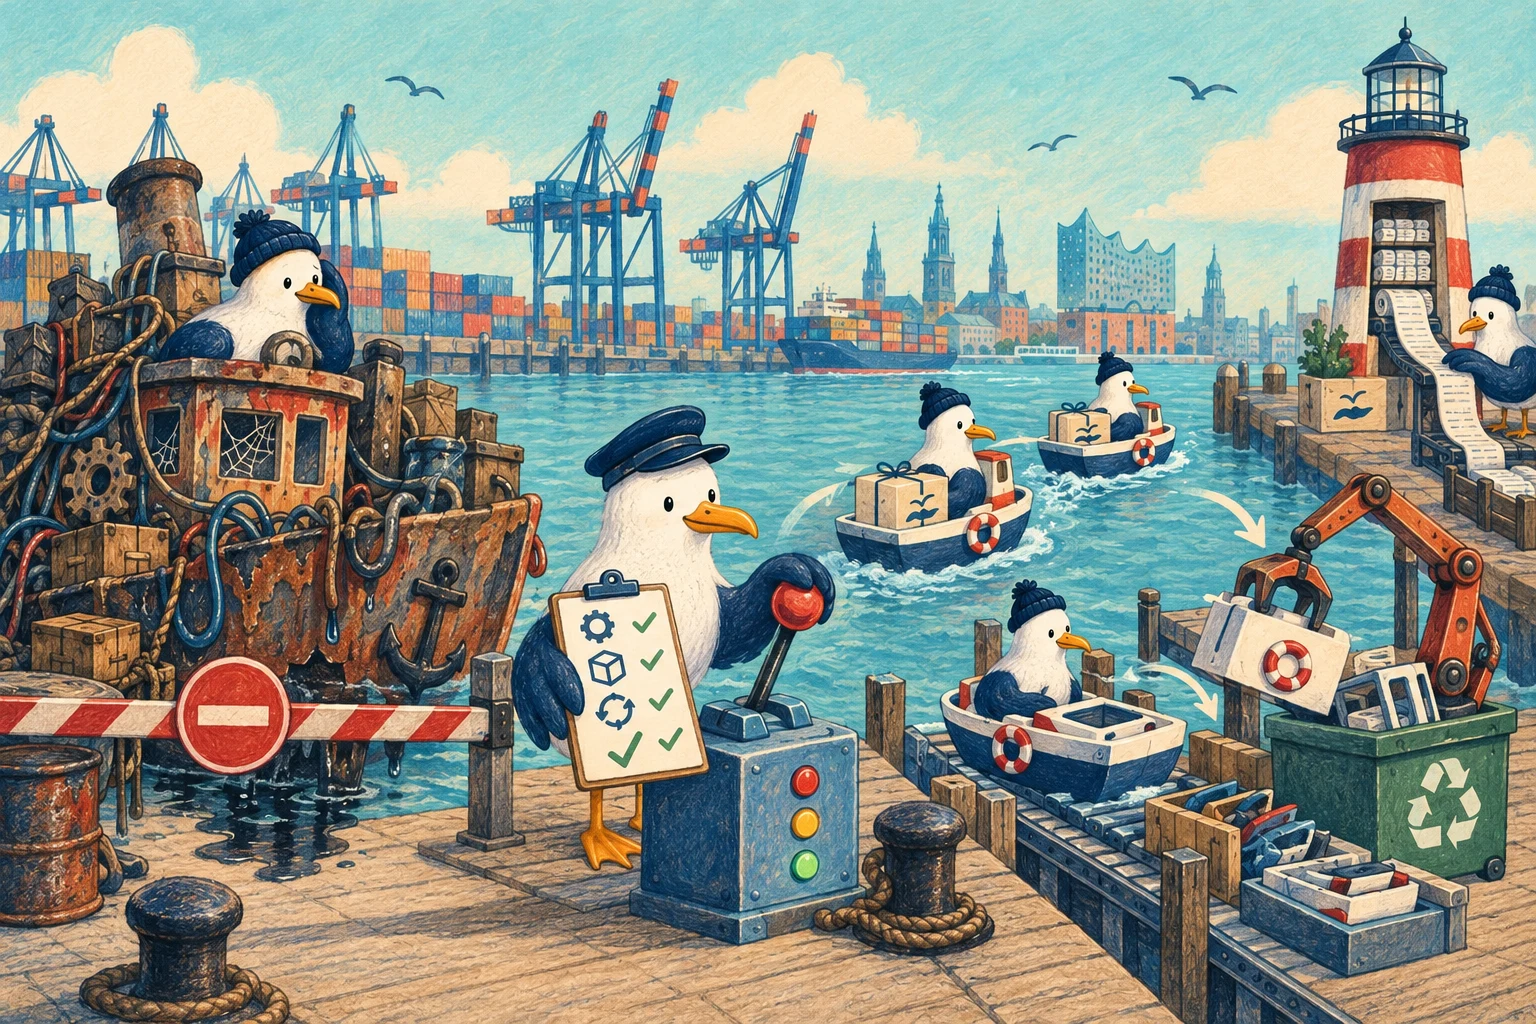
The immediate symptom looks harmless: deployments remain queued even though the machine is online. The underlying signal is bigger. A self-hosted runner is not a server that should be installed once and nursed for years. It executes externally defined code with access to source, artifacts, networks and often secrets. Treat it as a disposable tool: fresh for one job, gone afterwards.
This lesson is not specific to GitHub Actions. GitLab also warns against non-ephemeral runners shared across projects. When a team operates its own CI compute, it owns isolation, patching, logs and blast-radius control.
What a runner really executes
A pipeline is remote code execution with friendly YAML. A job can start shell commands, install packages, build containers and interpret files from the repository. Even a routine step such as npm install can run scripts. A test can reach network services. A build plugin can read environment variables.
More remains on a permanent runner than teams expect:
- workspaces and temporary files;
- Docker layers, images and volumes;
- package-manager caches;
- SSH configuration, cloud CLI sessions or credential helpers;
- processes that outlive a job;
- network access to internal services;
- artifacts from another project.
The next job does not start in a defined environment. It starts inside history. That creates two problems at once: builds become hard to reproduce, and a compromised job can influence the next one.
Ephemeral means exactly one assignment
GitHub explicitly recommends ephemeral runners for autoscaling and does not recommend persistent autoscaling runners. An ephemeral runner receives one job and is then deregistered. Infrastructure must genuinely remove the machine or container afterwards, not merely clear the working directory.
GitLab describes the same target for its Instance executor: capacity 1 and use count 1 give every job its own instance, deleted immediately after completion. In older Docker Machine setups, MaxBuilds = 1 follows the same principle.
Platform vocabulary differs, but the lifecycle is consistent:
- A job enters the queue.
- Automation creates an instance from a known image.
- The runner registers with short-lived credentials.
- Exactly one job runs.
- Required logs and artifacts leave the instance.
- The instance is completely destroyed.
“Ephemeral” is therefore not a label in the CI dashboard. It is a lifecycle guarantee that can be verified.
The image becomes the product
When machines live briefly, configuration moves into a versioned image. It contains the operating system, runner, build tools, certificates and the small set of utilities the job genuinely needs. Changes pass through the same review process as application code.
A useful runner image answers four questions:
- Which immutable base produced it?
- Which runner and toolchain versions does it contain?
- When was it last rebuilt and tested?
- Which pipelines may use it?
GitHub updates the runner application automatically by default. In container images, that can produce unnecessary downloads on every start. Teams using --disableupdate take explicit responsibility for rebuilding the image inside the supported window. Importantly, updating the runner does not patch the operating system, Docker, browsers, SDKs or other tools. Those need their own patch cadence.
In practice, rebuild images regularly rather than waiting for a warning. A nightly build can absorb patches; a short smoke test verifies registration, checkout, caching, artifact upload and network access. Only then should the new image digest become available to jobs.
Trust zones instead of one giant runner pool
A runner processing pull requests carries a different risk from a runner deploying production. Putting both in the same pool connects untrusted code to valuable permissions.
We separate at least three zones:
Untrusted checks: Tests for external or unapproved changes. No production secrets, no internal network, read-only token and an ephemeral instance.
Trusted build: Runs after review or on protected branches. It may sign artifacts or write to a registry, but still has no direct production access.
Deploy: Uses a previously built, uniquely identified artifact. Approval is separate, secrets are scoped to this job and the environment can reach only required destinations.
A pipeline is not secured by a single “if branch equals main” expression. Boundaries need to exist in runner groups, network rules, identities and secret policies.
Pull requests are outside code
In November 2026, GitHub will enforce a stricter default pull_request_target policy for affected public repositories. That trigger runs in the base repository context and may see privileged tokens or secrets. If the workflow then checks out and executes a fork's code, it creates the classic pwn-request vulnerability.
The safe default is to use pull_request for ordinary checks. If a privileged follow-up is necessary, treat inputs as data, minimise permissions and separate the trusted step clearly. A self-hosted runner for untrusted pull requests should reach neither internal services nor a second job.
The obvious build command is not the only execution point. Dependencies, build configuration, test fixtures and downloaded artifacts can all run code. “We only start tests” is not a security boundary.
Give secrets late and for a short time
A long-lived cloud password on a runner disk conflicts with the ephemeral model. Prefer short-lived, job-bound identities: the job proves which workflow and repository launched it, then receives a narrowly scoped token for that run.
Where that is not possible:
- expose secrets only to trusted jobs;
- scope values to one environment and purpose;
- do not confuse masking with protection;
- automate rotation;
- minimise write permissions and network destinations;
- never bake secrets into images, caches or artifacts.
An ephemeral runner reduces the time stolen data remains on a machine. It does not replace a sound permission model.
Caches and artifacts are different things
A cache accelerates the next build. An artifact is a result passed forward with a traceable identity. Mixing the two makes old, mutable data the foundation of a release.
Untrusted jobs should not overwrite caches later consumed by trusted jobs. Cache keys need dependencies, platform and relevant lockfile hashes. Releases should use immutable artifacts with a digest, provenance and explicit retention — not whichever directory happened to survive on the last runner.
A clean runner can still load a bad input. Isolation protects the machine; provenance protects the path of the output.
Logs must outlive the runner
A discarded runner takes its local diagnostics with it. GitHub therefore explicitly recommends forwarding ephemeral runner logs to external storage. That means more than the visible job log: creation, registration, image version, instance ID, deletion and infrastructure failures should be recorded too.
After an incident, the team should be able to answer:
- Which image digest ran?
- When was the instance created and deleted?
- Which job and repository were assigned?
- Could the runner reach required services?
- Was the complete log delivered?
Keep those records for a defined period and keep secrets out of them. Without external logs, ephemeral compute turns into blind flying at the first failure.
A realistic migration without a big bang
The change does not have to begin with a Kubernetes cluster. For a modest workload, a hosted runner can be safer and cheaper than maintaining a private fleet. Where special hardware, private networks or licensed tools make self-hosting necessary, migrate in stages:
- Inventory runners, versions, owners, projects and network reach.
- Update outdated runners immediately and watch queue annotations.
- Move untrusted and privileged jobs into separate groups.
- Build a reproducible image for the most common job.
- Migrate one pipeline type to one-job instances.
- Prove log export and instance deletion outside the instance.
- Measure caches, cost and startup time, then scale.
Success is not simply “the job runs again”. The migration succeeds when the instance owns nothing after the job that could influence the next one.
CI is production infrastructure
The new version enforcement exposes a truth that was already there: a self-hosted runner is part of the software supply chain. It needs patch windows, named owners, minimal permissions, external observability and a tested replacement path.
The strongest simplification is radically small: one pipeline, one fresh machine and one clear output. Cleanup happens by making the machine disappear.
Sources