11 October 2026 · 10 min
Tools are not enough: skills make agents operational
Cloudflare started shipping working instructions with its MCP server on 10 October. What Skills over MCP means for dependable agents, security and measurable automation.
A toolbox is not a workflow
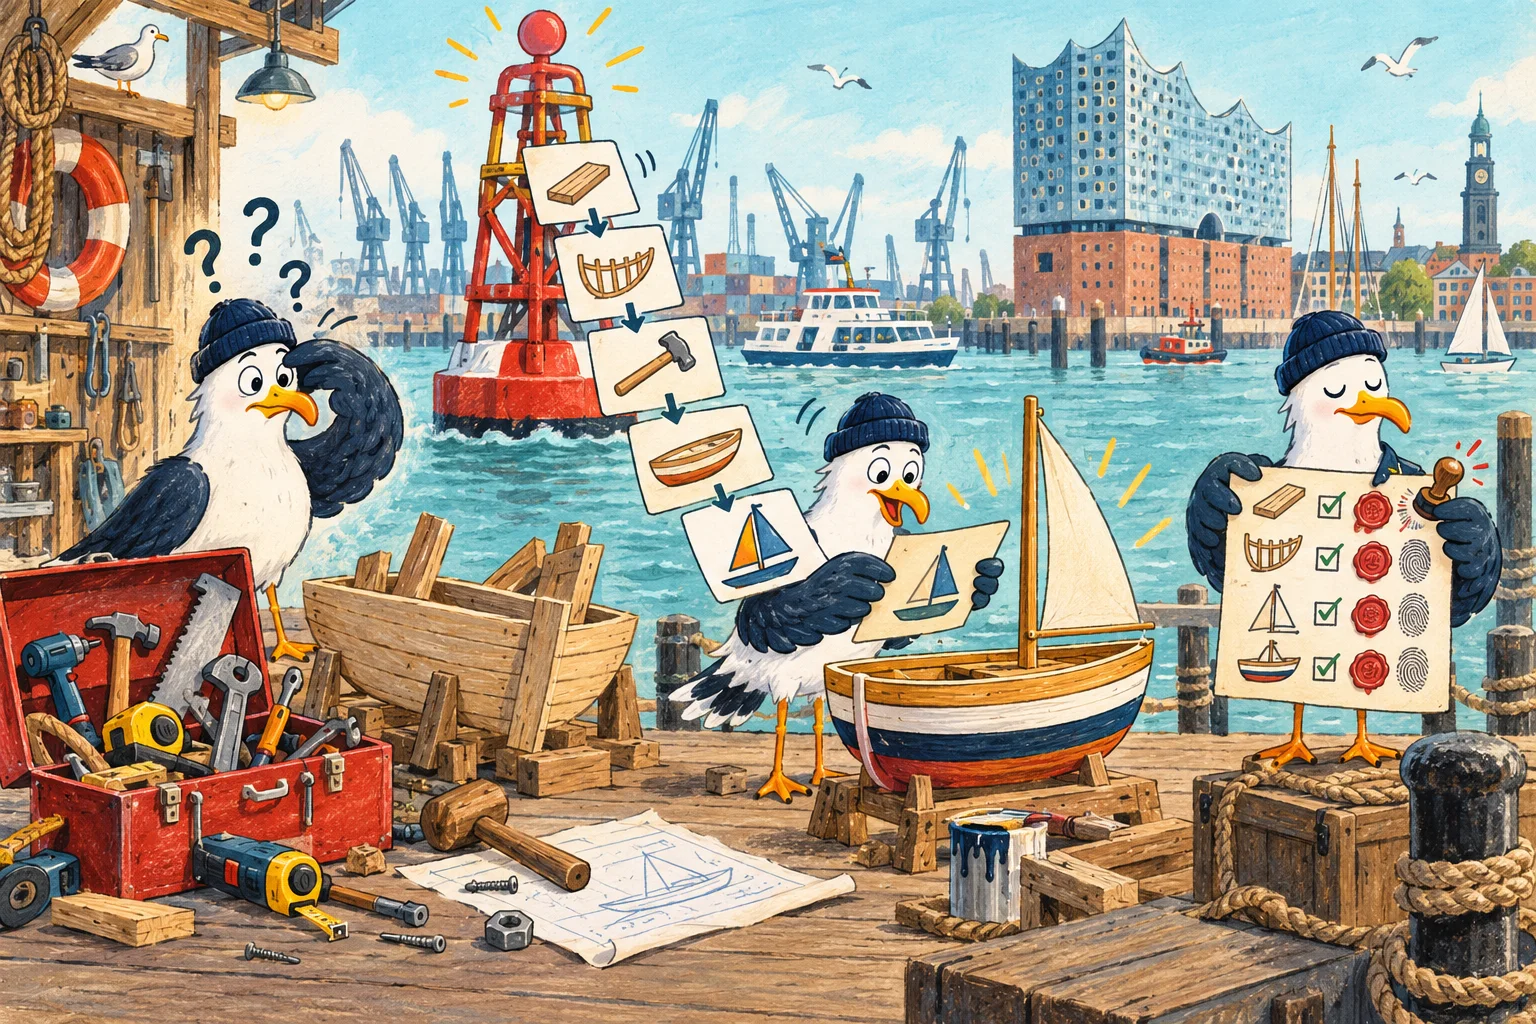
Many agent projects begin with the same demo: the model sees ten tools, chooses one and produces an impressive result. Daily use exposes the missing layer. The agent knows the API, but not the order of operations, the team's exceptions, the required checks or the point where a human should take over.
On 10 October 2026, Cloudflare added an interesting second layer to its API MCP server. Supported clients can now discover relevant skills through skills/list and read their files as skill:// resources. The technical capability — deploying a Worker or configuring a zone, for example — can now travel with structured operating instructions.
This may sound like a small protocol detail. For production automation it is an architectural change. A tool describes what a system can execute. A skill explains how to use those capabilities to reach one goal safely and repeatably.
Tools, resources and skills have different jobs
The terms should remain separate:
- Tools are executable actions with defined inputs and outputs.
- Resources provide data or documents without defining a workflow.
- Skills contain workflow knowledge: prerequisites, sequence, boundaries, verification and recovery.
A deployment tool might accept a project, artefact and environment. Its skill additionally explains how to build the artefact, which smoke tests run before release, when to choose preview rather than production and how to roll back after a failure.
This separation keeps the API small. Instead of creating twenty slightly different “deploy the way our team does it” tools, the action stays stable while the operating method becomes a reviewable, versioned instruction set.
What the extension actually standardises
The stable Skills over MCP extension is named io.modelcontextprotocol/skills. A server declares it during capability negotiation. Two methods are required and one is optional:
- skills/list returns the skills the server offers, with pagination where needed.
- skills/get retrieves the current entry for one skill by URI.
- resources/directory/read may list directories when the server supports directoryRead.
A skill contains at least a SKILL.md with a name and description. References, scripts, examples and assets can live beside it. Files are not transferred as one opaque archive; they are read individually through the existing resources/read mechanism.
The listing entry also carries a manifest of URIs, file sizes and SHA-256 digests. The specification sets limits of 512 resources and 16 MiB in total per skill. This bounds the surface and lets a host verify files against the state it previously observed.
Progressive disclosure keeps context focused
An agent does not need every runbook, example and template for every task. A name and description are enough to select a likely skill. The SKILL.md is fetched only when the skill is activated; supporting files follow only when needed.
This is not merely a token optimisation. It prevents irrelevant instructions from competing. A billing workflow does not need DNS migration rules, log-analysis recipes and image-optimisation guidance in the same context.
For skill authors, that implies a clear structure:
- The description should state precisely when the skill applies — and when it does not.
- SKILL.md contains the shortest complete happy path.
- Detailed knowledge moves into named references.
- Scripts automate deterministic work instead of asking the model to reinvent it.
- Examples show realistic inputs and outputs, not only one lucky demo.
A skill needs a testable definition of done
Weak skills are long prompts written in a friendly tone. Strong skills model a process an experienced colleague could actually review.
Every production skill should answer at least these questions:
- Which inputs must exist before work begins?
- Which systems and permissions are allowed?
- Which steps are deterministic and which require model judgement?
- Which intermediate states must be checked?
- Which side effects require confirmation?
- What counts as success?
- How is a partial failure detected and handled?
- Which information must never enter logs or model context?
A content-publishing skill, for example, does not finish at “upload the article”. Done means both languages exist, links are valid, the image format is correct, the build passes, the preview is checked, publication is confirmed and the URL is reachable. That definition separates text generation from a dependable publishing process.
Remote skills are not trusted by default
The official specification is refreshingly explicit here: skill content is untrusted input and a prompt-injection surface. A connected server does not become authoritative simply because it serves instructions beside its tools.
A host must preserve origin and treat remote skills differently from local team policy. Four boundaries are especially important:
- A remote skill must not silently shadow a same-named local skill.
- It must not widen tool or filesystem permissions through allowed-tools.
- Host-side code execution requires explicit approval for that skill.
- Resource reads stay bound to the originating server; a skill from server A must not quietly read from server B.
Nested skills do not inherit consent either. If an approved skill contains another skill, the nested one needs its own activation. That friction is the security boundary working as intended.
Digests prove consistency, not trust
The manifest enables one valuable check. If the size or SHA-256 digest of a fetched file differs from its entry, the host must not use it. When the resource set changes, any approval bound to the previous set must be revoked and requested again.
A matching digest is still not an endorsement. The same server supplies both manifest and content. A malicious server or compromised intermediary can alter both together. The digest proves that the bytes match the announced snapshot; it does not prove that the instruction is safe, sensible or written by the claimed author.
Teams still own provenance, review and permission. Technical integrity cannot replace a supply-chain decision.
Decide where each kind of knowledge lives
Not every rule belongs on one server. We divide skill knowledge into three layers:
- Vendor knowledge stays with the MCP server: current API behaviour, accepted parameters, safe ordering and product-specific recovery.
- Team knowledge lives in your own reviewable skills: naming, quality gates, approvals and operating policy.
- Task context arrives at runtime: the actual project, environment and desired result.
A Cloudflare skill can explain how to build a Worker correctly with bindings and streaming. It should not decide which production zone the MÖWE team may change without confirmation. That boundary belongs in our policy and a human approval step.
Putting everything into one universal skill couples vendor changes, internal governance and individual tasks again. Small skills with explicit ownership are easier to test and replace.
Skills need releases like code
Operating instructions change production behaviour, so they need a software lifecycle:
- a named owner;
- review before publication;
- traceable changes;
- tests for normal and dangerous paths;
- staged rollout;
- a route back to a known state.
The MCP extension binds consent to URIs and digests, but it does not define a product-versioning scheme for a skill's meaning. Teams must decide how to signal breaking changes and how long old workflows remain supported.
Quiet changes to thresholds, new write actions and access to additional systems are particularly risky. They are not copy edits. They change the agent's blast radius.
Measure the workflow, not the pretty output
One screenshot cannot prove that a skill helps. A compact evaluation set should contain repeated work and uncomfortable edge cases. Useful metrics include:
- percentage of tasks completed end to end;
- unnecessary or incorrect tool calls;
- sequence and approval violations;
- human corrections before completion;
- recovery rate after partial failures;
- context use and execution time;
- regressions after a skill update.
Compare at least three variants: tools without a skill, tools with the current skill and tools with the proposed new version. The update belongs on the default path only when it produces a measurable improvement in completion or safety.
A pragmatic starting point
Cloudflare's launch shows where MCP is heading, but client support is not yet complete everywhere. The public implementation matrix lists some hosts as v1 or partial while several official SDK integrations remain in progress. Before rollout, confirm that your host really implements extension negotiation, skills/list, skills/get, digest verification and approvals.
For a first project:
- choose one frequent, tightly bounded workflow;
- separate tool actions from process knowledge;
- write a short SKILL.md with only a few focused references;
- mark dangerous side effects and human stops explicitly;
- collect ten to twenty real tasks as an evaluation set;
- enable the skill for one team or environment only;
- measure failures, approvals and manual corrections;
- expand to other workflows only after a demonstrated gain.
The important advance is not that agents can read more documentation. It is that capability and operating method can be shipped separately, verified independently and changed under control. An agent with tools can act. A well-governed agent with skills can finish the job reliably.
Sources